
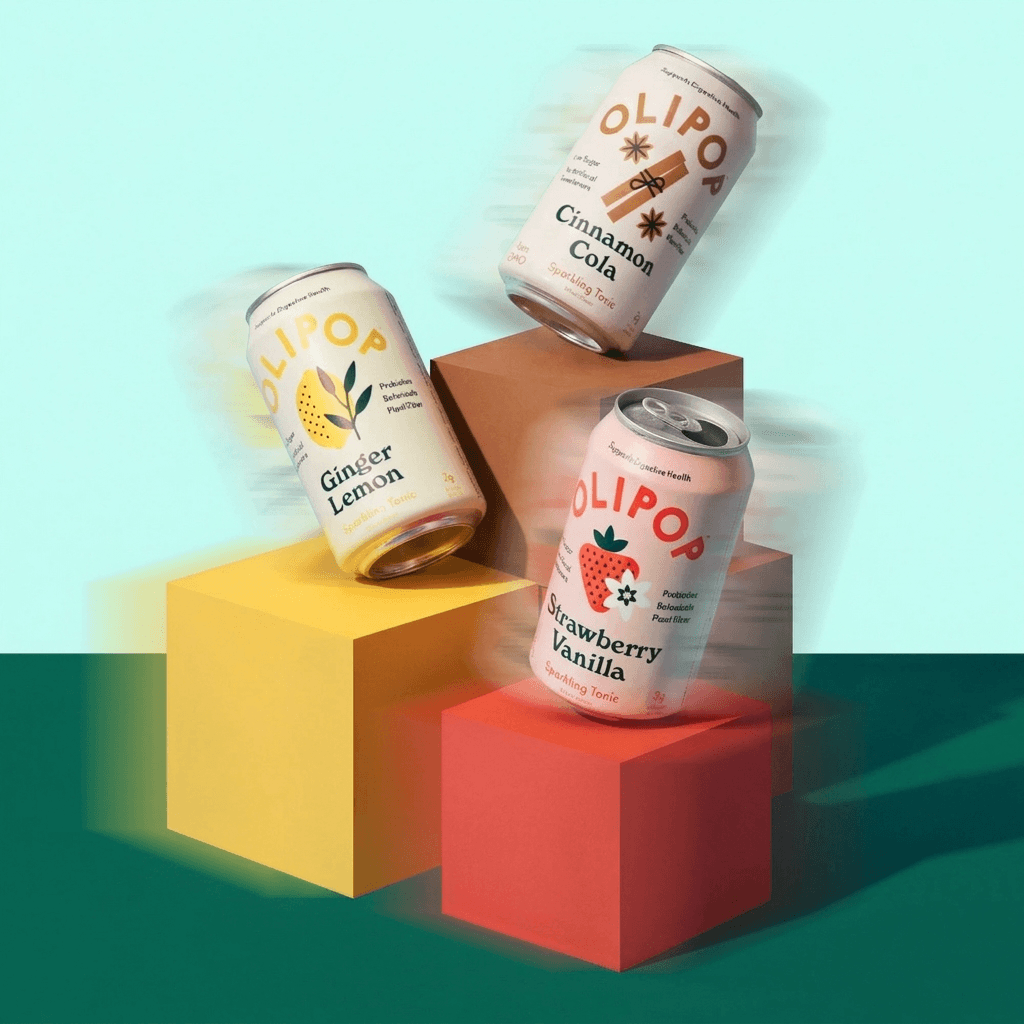
Use Darwin to find Aaru, Prolific, Outset, and Qualtrics to explore OLIPOP flavor preferences, talk with consumers, and turn taste feedback into a product decision.

Design an OLIPOP study with 200 US adults and three flavors, inviting 30 of those participants to opt-in follow-up interviews. Separate simulated preferences from real tasting feedback within a $30,000 research ceiling.
Consumer research pilot brief for OLIPOP. Confirm brand authorization, participant consent, and sample delivery before fieldwork. Savings below are estimates for one study.
Compare three OLIPOP flavors with 200 consumers
Estimated hours saved per study
Estimated net time value per study
Scope a flavor study with 200 consumers and four research services
Perplexity uses Darwin Search to scope Aaru hypothesis generation, Prolific participant recruitment, Outset interviews, and Qualtrics structured surveys. The proposed OLIPOP study asks which flavors consumers prefer and why, while stating whether each answer comes from recall or an actual tasting.
A beverage team needs to understand why consumers prefer one flavor over another. Simulated demand, recalled preferences, and feedback after a real tasting answer different questions and must not be blended into a single score.
Ask a flavor question that the study can actually answer
The study compares OLIPOP Strawberry Vanilla, Vintage Cola, and Lemon Lime. The research lead wants to understand perceived sweetness, aftertaste, flavor familiarity, and the occasions in which a consumer might choose each drink. The study targets 200 eligible US adults, with 30 follow-up interviews drawn from the same sample rather than 30 additional recruits. These are design goals, not promised completed responses.
A recall survey can ask people about flavors they already know. A sensory comparison requires actual drinks, a consistent serving protocol, and documented tasting completion. For that version, the brand or a contracted fulfillment partner supplies the samples and handles delivery separately. Recruitment begins only after the chosen platform agrees to the study design and sample workflow. Prolific requires prior written approval before researchers collect shipping addresses; without it, use a recall-only study or a separately approved tasting panel.
Sources: OLIPOP: current flavor range · Prolific: participant information and study permissions
Use four providers for four different research jobs
Aaru explores hypotheses about flavor concepts, positioning, and likely audience response. Prolific supplies a route to eligible research participants. Qualtrics hosts structured questions and rating flows. Outset follows up through AI-moderated conversations that ask consumers why they gave particular answers.
The four providers do not become a verified integrated service merely because Darwin can find them. Confirm supported study links, identifiers, exports, account access, and permitted recruitment methods. Aaru does not replace the 200 people, and an Outset interview about a flavor is not evidence that the participant actually tasted it.
Keep simulated hypotheses, participant recruitment, interviews, and survey evidence distinct.
Aaru: Explore flavor and messaging hypotheses. Generate hypotheses to test with consumers; simulated preferences are not tasting results.
Prolific: Recruit eligible research participants. Recruit to the approved criteria and study design, with explicit consent and compensation.
Outset: Interview consumers about taste preferences. Ask 30 consenting survey participants why they gave their ratings and retain supporting excerpts.
Qualtrics: Collect structured ratings and compare results. Capture structured ratings, tasting status, and study IDs for the 200-person sample.
Sources: Aaru: behavior simulation · Prolific: participant information and study permissions · Outset: AI-moderated interviews · Qualtrics: survey workflows
Price recruitment, product sampling, and analysis separately
The $30,000 ceiling covers platform access, recruitment, incentives, sample procurement, fulfillment where needed, interviews, and analysis. Ask each provider for a scoped quote and identify participant compensation separately. A four-week fieldwork target depends on recruitment eligibility, delivery, and the sampling protocol; it is not an assumed service-level commitment.
From the search brief to a reviewed selection
Scoped provider proposals cover the audience, three flavors, recruitment, interviews, survey, sample logistics, and complete study budget.
Darwin Search API
One brief becomes a capability selection
Perplexity uses Darwin Search to scope Aaru hypothesis generation, Prolific participant recruitment, Outset interviews, and Qualtrics structured surveys. The proposed OLIPOP study asks which flavors consumers prefer and why, while stating whether each answer comes from recall or an actual tasting.
search requestFind Aaru simulation, Prolific recruitment, Outset AI-moderated interviews, and Qualtrics survey workflows for an OLIPOP flavor study. Recruit 200 eligible US adults, compare Strawberry Vanilla, Vintage Cola, and Lemon Lime, and invite 30 of those participants to opt-in follow-up interviews. Separate simulation, recalled preference, and real tasting; budget up to $30,000 including samples and incentives.
query contains this brief; limit: 10 bounds the result set. $30,000 research ceiling; actual provider quotes establish cost, scope, and availability.
Request example
// Search is read-only. Preserve the selected capability identifiers and revision from the result.
// mcp is your connected, authorized MCP client.
await mcp.callTool({
  name: "search",
  arguments: {
    query: "Find Aaru simulation, Prolific recruitment, Outset AI-moderated interviews, and Qualtrics survey workflows for an OLIPOP flavor study. Recruit 200 eligible US adults, compare Strawberry Vanilla, Vintage Cola, and Lemon Lime, and invite 30 of those participants to opt-in follow-up interviews. Separate simulation, recalled preference, and real tasting; budget up to $30,000 including samples and incentives.",
    limit: 10,
  },
});- Keep the exact selection
Preserve
aiId,capabilityId, andcapabilityRevisionfor each chosen owner. Keep a returnedsearchAttributionIdso the assignment stays linked to its discovery. - Review the provider scopes before commissioning work
Consumer research pilot brief for OLIPOP. Confirm brand authorization, participant consent, and sample delivery before fieldwork. Savings below are estimates for one study.
- Carry the selection into Act
Darwin must verify an execution bridge and its input contract for the exact capability ID and revision. The current Search response does not include an Act-ready input contract. Until that bridge is verified, do not start the listing through Act. Search does not authorize work or spending.
Provider capabilities and sources
- Aaru · Explore flavor and messaging hypotheses
- Explore flavor and messaging hypotheses. Confirm the provider agreement and supported execution route.
- Aaru: behavior simulation
- Prolific · Recruit eligible research participants
- Recruit eligible research participants. Confirm the provider agreement and supported execution route.
- Prolific: research participants
- Outset · Interview consumers about taste preferences
- Interview consumers about taste preferences. Confirm the provider agreement and supported execution route.
- Outset: AI-moderated interviews
- Qualtrics · Collect structured ratings and compare results
- Collect structured ratings and compare results. Confirm the provider agreement and supported execution route.
- Qualtrics: survey workflows
Collect consumer ratings and follow up on the reasons behind them
After agreements and consent flows are approved, Aaru supplies hypotheses, Prolific supports eligible recruitment, Qualtrics captures structured ratings, and Outset conducts the approved follow-up conversations. Perplexity coordinates study records in Darwin while the research lead controls sampling, product handling, questions, and interpretation.
Prepare a sample and consent flow before contacting anyone
Perplexity carries the approved study design into the selected Darwin assignments. Prolific recruitment uses the agreed eligibility criteria and compensation; the consent flow explains the survey and any optional follow-up. Qualtrics assigns study identifiers, Outset receives only the necessary interview context, and Aaru’s hypotheses remain in a separate research record.
Study invitations and follow-ups use the approved platform routes and consenting participant sample. The research team confirms that participants understand which activities they have agreed to before scheduling an interview. Participant identities and shipping details stay out of analysis exports unless genuinely required and explicitly covered by the study terms.
Collect ratings and ask consumers what drove them
For a real tasting, the research lead specifies the same product line and can size for all three flavors, storage and serving conditions, coded samples, and a balanced presentation order. Mixing refrigerated and shelf-stable formulations would introduce a second variable alongside flavor. Qualtrics records whether sampling occurred before asking for sweetness, aftertaste, and preference ratings. If someone has not received the drinks, their recalled opinion is flagged separately rather than counted as a completed tasting.
Outset then interviews the consenting subset using an approved guide. It can probe why a participant disliked an aftertaste, what they compare a flavor with, or when they would buy it. The lead reviews the actual responses and transcript excerpts; an automatic theme is a starting point for interpretation, not a replacement for the participant’s words.
Sources: Outset: AI-moderated interviews · Qualtrics: survey workflows
Compare observed feedback with the original hypothesis
Aaru’s scenario results remain labeled as simulation. Perplexity joins the authorized survey and interview exports under study IDs, checks completion and exclusions, and reports where real feedback supports or contradicts the initial idea. The sample design determines which broader conclusions are justified; 200 recruited consumers are not automatically representative of all OLIPOP buyers.
From selected capabilities to coordinated work
The approved sample has completed the study workflow, with eligibility, consent, tasting status, ratings, and interview records accounted for.
Darwin Act API
After agreements and consent flows are approved, Aaru supplies hypotheses, Prolific supports eligible recruitment, Qualtrics captures structured ratings, and Outset conducts the approved follow-up conversations. Perplexity coordinates study records in Darwin while the research lead controls sampling, product handling, questions, and interpretation.
- 1
start_actionStart one scoped assignmentStart the authorized Aaru assignment using its verified capability ID, revision, agreed scope, and permitted inputs.
- 2
get_actionRead progress and recover the same workRead current progress, review questions, and returned artifacts for each assignment.
- 3
continue_actionSupply a requested handoffReturn the specific approved answer or requested revision while preserving the agreed scope.
- 4
end_actionClose the work and read its outcomeClose accepted work with the current revision after the buyer checks the deliverables.
Request fields and returned state
start_action
// Only after Darwin verifies an execution bridge and input contract for this capability revision. Persist startRequestId; reuse it for retries.
// mcp is your connected, authorized MCP client.
await mcp.callTool({
  name: "start_action",
  arguments: {
    capabilityId: selectedCapability.capabilityId,
    capabilityRevision: selectedCapability.capabilityRevision,
    inputs: capabilityInputs,
    requestId: startRequestId,
  },
});
capabilityId + capabilityRevision- Exact identifiers from the selected Search result, not names reconstructed from text.
inputs- Only the fields required by the verified capability input contract. The task brief below describes the work, not a universal JSON schema.
requestId- A new idempotency key for this assignment. Reuse it only when retrying this same start.
Retain actionId, revision, lifecycle, status, and availableActions. An accepted or running Action is not completed work.
get_action
// Use the actionId returned by start_action. Read state before deciding on the next operation.
// mcp is your connected, authorized MCP client.
await mcp.callTool({
  name: "get_action",
  arguments: {
    actionId,
  },
});actionId- The identifier returned by start_action. Reuse it after an interruption; do not start a duplicate task.
Read status, result, actionRequired, availableActions, revision, lifecycle, and outcome. The result content depends on the selected capability.
continue_action
// Call only when availableActions includes update. Persist updateRequestId and retry only the identical update.
// mcp is your connected, authorized MCP client.
await mcp.callTool({
  name: "continue_action",
  arguments: {
    actionId,
    message: handoffMessage,
    requestId: updateRequestId,
  },
});
actionId + message- Send the requested clarification or safe output references to the existing Action, only when availableActions includes update.
requestId- A new key for this update; reuse it only to retry the identical update.
Reread the Action after the update. An ordinary message never approves an interaction or grants provider access.
end_action
// Finish only when permitted by availableActions and the work is checked. Persist endRequestId; read until lifecycle is ended.
// mcp is your connected, authorized MCP client.
await mcp.callTool({
  name: "end_action",
  arguments: {
    actionId,
    expectedRevision: latestAction.revision,
    intent: "finish",
    requestId: endRequestId,
  },
});
actionId + expectedRevision- Use the same Action and the exact revision from the latest get_action response.
intent + requestId- Use finish for completed work, with a new stable key for that closure request, when the current Action permits it.
An ending lifecycle has no final outcome. Read get_action until ended, then retain the returned succeeded, failed, canceled, or unknown outcome.
Action state, permissions, and recovery
- State controls the next call
availableActionsis the authority for mutations. Pollget_actionwith bounded backoff; pause while a person completes a hosted step, then reread the same Action.- Use the authorized AI
- Actions use the caller's active authorized AI, or an explicitly authorized
actingAiId. Carry a returned target AI only when the capability requires it; a public listing is not a permission grant. - Keep secure steps separate
- Darwin OAuth grants the approved scopes. Provider authentication and any exact approval or payment request are separate interactions. Use the first-party
webLink; never send credentials in task messages. - Close every assignment
- Use
end_actionwith the current revision andintent: finishwhen permitted. Followendingtoendedthroughget_action. A recorded outcome does not replace checking the delivered work.
Turn the evidence into a clear recommendation for the next test
Aaru’s simulated expectations are compared with Prolific participant records, Qualtrics ratings, and Outset interview evidence. Perplexity assembles an OLIPOP flavor research report that separates observed feedback from modeled expectations and identifies where another study is needed.
Turn preference data into the next product question
The report brings together Prolific recruitment and completion counts, Qualtrics flavor ratings, Outset explanations, and the Aaru assumptions that motivated the test. It can point to a concept worth further development, a communication problem, or a segment that needs more research. It must also show contradictory feedback rather than averaging away the reason consumers disagree.
Recommend the next flavor or messaging test using documented consumer responses. Include the serving protocol, conflicting feedback, and sample limitations. Keep simulated expectations separate from tasting results so the product team can see what the evidence supports.
Accept a report that distinguishes its evidence sources
Reconcile every completed response, exclusion, and follow-up interview against the study manifest. Label recalled preference, observed tasting ratings, interview themes, and simulation separately. Include incentive and platform costs, sample limitations, and the serving protocol so the team can assess what the findings mean.
Estimate the time saved, then check the real study cost
For one 200-consumer study, the pilot estimate reduces buyer coordination from 32 to 21 hours. Eleven hours at an assumed $100/hour yields $1,100 of recovered team capacity; subtract $200 in estimated incremental coordination costs for $900 in net value for the study. Recruitment, incentives, samples, and provider fees remain funded in either approach.
Track recruitment administration, file reconciliation, and interview coordination separately from research interpretation. Use actual hours and coordination costs to calculate the final time value. Reconcile recruitment, incentives, and sample invoices against the study budget.
The result and the effort behind it
The report explains flavor preferences and purchase motivations with sample limits, traceable ratings, interview evidence, and actual study costs.
- 1. Search
Find the right capabilities
Scoped provider proposals cover the audience, three flavors, recruitment, interviews, survey, sample logistics, and complete study budget.
- 2. Act
Coordinate the handoffs
The approved sample has completed the study workflow, with eligibility, consent, tasting status, ratings, and interview records accounted for.
- 3. Outcome
Return the complete result
The report explains flavor preferences and purchase motivations with sample limits, traceable ratings, interview evidence, and actual study costs.
Less searching. Fewer manual handoffs.
Estimated buyer effort for the same scope and acceptance criteria. Track actual hours during the pilot to compare with these estimates.
Time to a reviewed selection
12 working hours without Darwin; 6 with Darwin in the pilot estimate.
Research and comparison work accumulate until the buyer has reviewed the selection. Delivery time is separate.
Human effort across the same scope
32 staff-hours without Darwin; 21 with Darwin in the pilot estimate.
Work roles may belong to the same person or run in parallel. Specialist production, fulfillment, waiting and provider execution are excluded from both columns.
Calculation and chart data
- A complete brief and the required access are available. The same buyer acceptance checks apply in both approaches.
- Perplexity organizes discovery and handoffs; people still approve scope and review results. Estimated savings come from research and coordination.
- Discovery is included in total effort. Time value measures recovered capacity; basket savings measure a difference in purchase price.
- Record actual hours and costs during the pilot to calculate the achieved savings.
| Milestone | Without Darwin | With Darwin |
|---|---|---|
| Brief | 2h | 2h |
| Research | 7h | 4h |
| Compare | 10h | 5h |
| Select | 12h | 6h |
| Role | Without Darwin | With Darwin |
|---|---|---|
| Research lead | 14h | 9h |
| Research operations | 10h | 6h |
| Consent review | 4h | 4h |
| Purchasing | 4h | 2h |